
Fine Tuning Detr Custom Dataset
Fine-Tuning Object Detection Model on a Custom Dataset 🖼, Deployment in Spaces, and Gradio API Integration
Authored by: Sergio Paniego
In this notebook, we will fine-tune an object detection model—specifically, DETR—using a custom dataset. We will leverage the Hugging Face ecosystem to accomplish this task.
Our approach involves starting with a pretrained DETR model and fine-tuning it on a custom dataset of annotated fashion images, namely Fashionpedia. By doing so, we'll adapt the model to better recognize and detect objects within the fashion domain.
After successfully fine-tuning the model, we will deploy it as a Gradio Space on Hugging Face. Additionally, we’ll explore how to interact with the deployed model using the Gradio API, enabling seamless communication with the hosted Space and unlocking new possibilities for real-world applications.

1. Install Dependencies
Let's start by installing the necessary libraries for fine-tuning our object detection model.
2. Load Dataset 📁
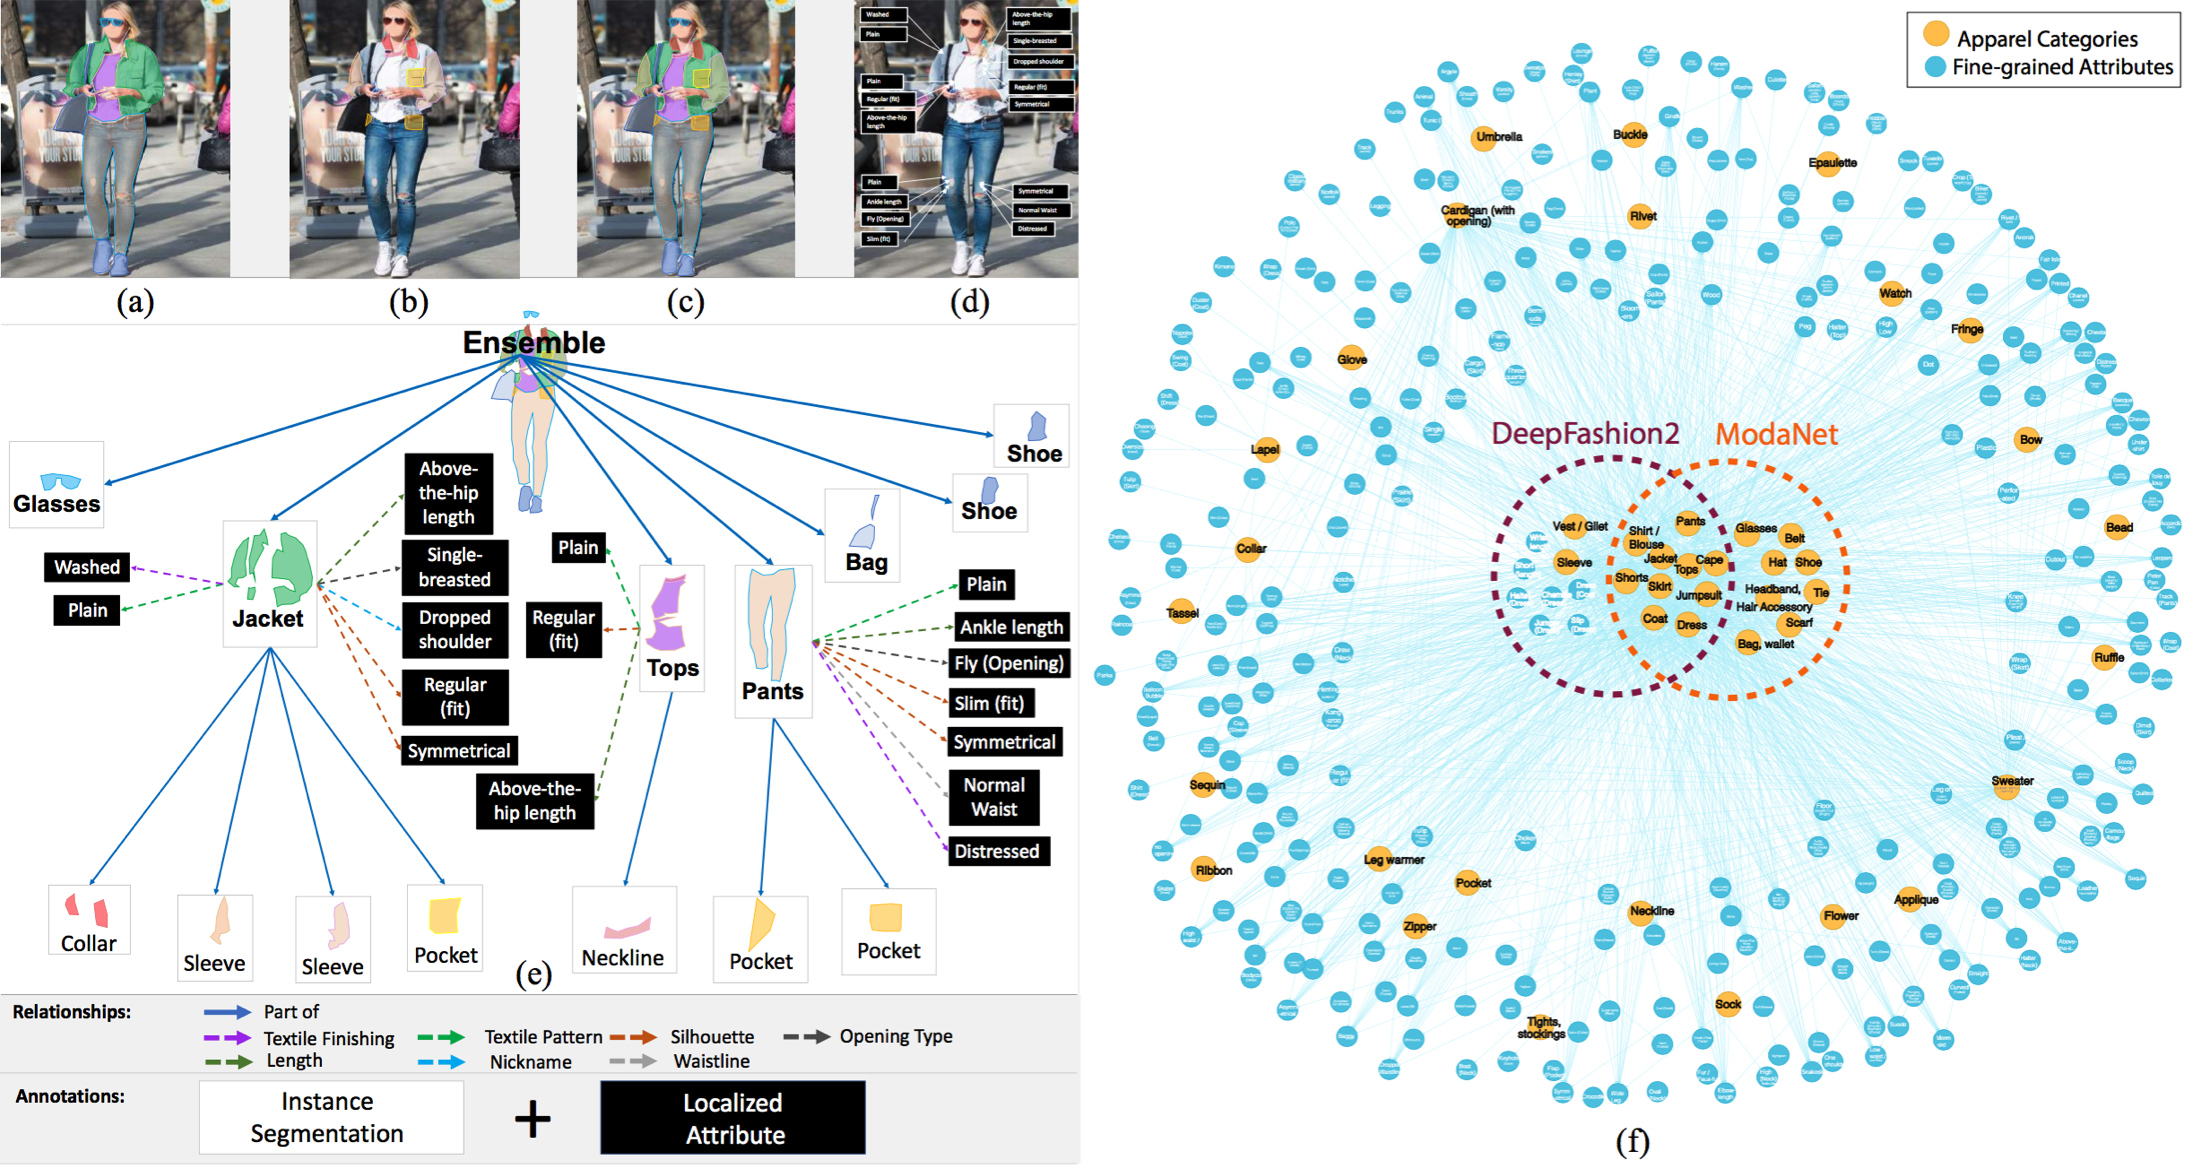
📁 The dataset we will use is Fashionpedia, which comes from the paper Fashionpedia: Ontology, Segmentation, and an Attribute Localization Dataset. The authors describe it as follows:
Fashionpedia is a dataset which consists of two parts: (1) an ontology built by fashion experts containing 27 main apparel categories, 19 apparel parts, 294 fine-grained attributes and their relationships; (2) a dataset with 48k everyday and celebrity event fashion images annotated with segmentation masks and their associated per-mask fine-grained attributes, built upon the Fashionpedia ontology.
The dataset includes:
- 46,781 images 🖼
- 342,182 bounding boxes 📦
It is available on Hugging Face: Fashionpedia Dataset
DatasetDict({
, train: Dataset({
, features: ['image_id', 'image', 'width', 'height', 'objects'],
, num_rows: 45623
, })
, val: Dataset({
, features: ['image_id', 'image', 'width', 'height', 'objects'],
, num_rows: 1158
, })
,}) Review the internal structure of one of the examples
{'image_id': 23,
, 'image': <PIL.JpegImagePlugin.JpegImageFile image mode=RGB size=682x1024>,
, 'width': 682,
, 'height': 1024,
, 'objects': {'bbox_id': [150311, 150312, 150313, 150314],
, 'category': [23, 23, 33, 10],
, 'bbox': [[445.0, 910.0, 505.0, 983.0],
, [239.0, 940.0, 284.0, 994.0],
, [298.0, 282.0, 386.0, 352.0],
, [210.0, 282.0, 448.0, 665.0]],
, 'area': [1422, 843, 373, 56375]}} 3. Get Splits of the Dataset for Training and Testing ➗
The dataset comes with two splits: train and test. We will use the training split to fine-tune the model and the test split for validation.
Optional
In the next commented cell, we randomly sample 1% of the original dataset for both the training and test splits. This approach is used to speed up the training process, as the dataset contains a large number of examples.
For the best results, we recommend skipping these two cells and using the full dataset. However, you can uncomment them if needed.
4. Visualize One Example from the Dataset with Its Objects 👀
Now that we've loaded the dataset, let's visualize an example along with its annotated objects.
Generate id2label and label2id
These variables contain the mappings between object IDs and their corresponding labels. id2label maps from IDs to labels, while label2id maps from labels to IDs.
Let's Draw One Image! 🎨
Now, let's visualize one image from the dataset to better understand what it looks like.
{'bbox_id': [158977, 158978, 158979, 158980, 158981, 158982, 158983], 'category': [1, 23, 23, 6, 31, 31, 33], 'bbox': [[210.0, 225.0, 536.0, 784.0], [290.0, 897.0, 350.0, 1015.0], [464.0, 950.0, 534.0, 1021.0], [313.0, 407.0, 524.0, 954.0], [268.0, 229.0, 333.0, 563.0], [489.0, 247.0, 528.0, 591.0], [387.0, 225.0, 450.0, 253.0]], 'area': [69960, 2449, 1788, 75418, 15149, 5998, 479]}

Let's Visualize Some More Images 📸
Now, let's take a look at a few more images from the dataset to get a broader view of the data.
{'bbox_id': [150311, 150312, 150313, 150314], 'category': [23, 23, 33, 10], 'bbox': [[445.0, 910.0, 505.0, 983.0], [239.0, 940.0, 284.0, 994.0], [298.0, 282.0, 386.0, 352.0], [210.0, 282.0, 448.0, 665.0]], 'area': [1422, 843, 373, 56375]}
{'bbox_id': [158953, 158954, 158955, 158956, 158957, 158958, 158959, 158960, 158961, 158962], 'category': [2, 33, 31, 31, 13, 7, 22, 22, 23, 23], 'bbox': [[182.0, 220.0, 472.0, 647.0], [294.0, 221.0, 407.0, 257.0], [405.0, 297.0, 472.0, 647.0], [182.0, 264.0, 266.0, 621.0], [284.0, 135.0, 372.0, 169.0], [238.0, 537.0, 414.0, 606.0], [351.0, 732.0, 417.0, 922.0], [202.0, 749.0, 270.0, 930.0], [200.0, 921.0, 256.0, 979.0], [373.0, 903.0, 455.0, 966.0]], 'area': [87267, 1220, 16895, 18541, 1468, 9360, 8629, 8270, 2717, 3121]}
{'bbox_id': [169196, 169197, 169198, 169199, 169200, 169201, 169202, 169203, 169204, 169205, 169206, 169207, 169208, 169209, 169210], 'category': [13, 29, 28, 32, 32, 31, 31, 0, 31, 31, 18, 4, 6, 23, 23], 'bbox': [[441.0, 132.0, 499.0, 150.0], [412.0, 164.0, 494.0, 295.0], [427.0, 164.0, 476.0, 207.0], [406.0, 326.0, 448.0, 335.0], [484.0, 327.0, 508.0, 334.0], [366.0, 323.0, 395.0, 372.0], [496.0, 271.0, 523.0, 302.0], [366.0, 164.0, 523.0, 372.0], [360.0, 186.0, 406.0, 332.0], [502.0, 201.0, 534.0, 321.0], [496.0, 259.0, 515.0, 278.0], [360.0, 164.0, 534.0, 411.0], [403.0, 384.0, 510.0, 638.0], [393.0, 584.0, 430.0, 663.0], [449.0, 638.0, 518.0, 681.0]], 'area': [587, 2922, 931, 262, 111, 1171, 540, 3981, 4457, 1724, 188, 26621, 16954, 2167, 1773]}
{'bbox_id': [167967, 167968, 167969, 167970, 167971, 167972, 167973, 167974, 167975, 167976, 167977, 167978, 167979, 167980, 167981, 167982, 167983, 167984, 167985, 167986, 167987, 167988, 167989, 167990, 167991, 167992, 167993, 167994, 167995, 167996, 167997, 167998, 167999, 168000, 168001, 168002, 168003, 168004, 168005, 168006, 168007, 168008, 168009, 168010, 168011, 168012, 168013, 168014, 168015, 168016, 168017, 168018, 168019, 168020, 168021, 168022, 168023, 168024, 168025, 168026, 168027, 168028, 168029, 168030, 168031, 168032, 168033, 168034, 168035, 168036, 168037, 168038, 168039, 168040], 'category': [6, 23, 23, 31, 31, 4, 1, 35, 32, 35, 35, 35, 35, 28, 35, 42, 42, 42, 42, 42, 42, 42, 42, 42, 42, 42, 42, 42, 42, 42, 42, 42, 42, 42, 42, 42, 42, 42, 42, 42, 42, 42, 42, 42, 42, 42, 42, 42, 42, 42, 42, 42, 42, 42, 42, 42, 42, 42, 42, 42, 42, 42, 42, 42, 42, 42, 42, 42, 42, 42, 42, 42, 42, 33], 'bbox': [[300.0, 421.0, 460.0, 846.0], [383.0, 841.0, 432.0, 899.0], [304.0, 740.0, 347.0, 831.0], [246.0, 222.0, 295.0, 505.0], [456.0, 229.0, 492.0, 517.0], [246.0, 169.0, 492.0, 517.0], [355.0, 213.0, 450.0, 433.0], [289.0, 353.0, 303.0, 427.0], [442.0, 288.0, 460.0, 340.0], [451.0, 290.0, 458.0, 304.0], [407.0, 238.0, 473.0, 486.0], [487.0, 501.0, 491.0, 517.0], [246.0, 455.0, 252.0, 505.0], [340.0, 169.0, 442.0, 238.0], [348.0, 230.0, 372.0, 476.0], [411.0, 179.0, 414.0, 182.0], [414.0, 183.0, 418.0, 186.0], [418.0, 187.0, 421.0, 190.0], [421.0, 192.0, 425.0, 195.0], [424.0, 196.0, 428.0, 199.0], [426.0, 200.0, 430.0, 204.0], [429.0, 204.0, 433.0, 208.0], [431.0, 209.0, 435.0, 213.0], [433.0, 214.0, 437.0, 218.0], [434.0, 218.0, 438.0, 222.0], [436.0, 223.0, 440.0, 226.0], [437.0, 227.0, 441.0, 231.0], [438.0, 232.0, 442.0, 235.0], [433.0, 232.0, 437.0, 236.0], [429.0, 233.0, 432.0, 237.0], [423.0, 233.0, 426.0, 237.0], [417.0, 233.0, 421.0, 237.0], [353.0, 172.0, 355.0, 174.0], [353.0, 175.0, 354.0, 177.0], [351.0, 178.0, 353.0, 181.0], [350.0, 182.0, 351.0, 184.0], [347.0, 187.0, 350.0, 189.0], [346.0, 190.0, 349.0, 193.0], [345.0, 194.0, 348.0, 197.0], [344.0, 199.0, 347.0, 202.0], [342.0, 204.0, 346.0, 207.0], [342.0, 208.0, 345.0, 211.0], [342.0, 212.0, 344.0, 215.0], [342.0, 217.0, 345.0, 220.0], [344.0, 221.0, 346.0, 224.0], [348.0, 222.0, 350.0, 225.0], [353.0, 223.0, 356.0, 226.0], [359.0, 223.0, 361.0, 226.0], [364.0, 223.0, 366.0, 226.0], [247.0, 448.0, 253.0, 454.0], [251.0, 454.0, 254.0, 456.0], [252.0, 460.0, 255.0, 463.0], [252.0, 466.0, 255.0, 469.0], [253.0, 471.0, 255.0, 475.0], [253.0, 478.0, 255.0, 481.0], [253.0, 483.0, 256.0, 486.0], [254.0, 489.0, 256.0, 492.0], [254.0, 495.0, 256.0, 497.0], [247.0, 457.0, 249.0, 460.0], [247.0, 463.0, 249.0, 466.0], [248.0, 469.0, 249.0, 471.0], [248.0, 476.0, 250.0, 478.0], [248.0, 481.0, 250.0, 483.0], [249.0, 486.0, 250.0, 488.0], [487.0, 459.0, 490.0, 461.0], [487.0, 465.0, 490.0, 467.0], [487.0, 471.0, 490.0, 472.0], [487.0, 476.0, 489.0, 478.0], [486.0, 482.0, 489.0, 484.0], [486.0, 488.0, 489.0, 490.0], [486.0, 494.0, 488.0, 496.0], [486.0, 500.0, 488.0, 501.0], [485.0, 505.0, 487.0, 507.0], [365.0, 213.0, 409.0, 226.0]], 'area': [44062, 2140, 2633, 9206, 5905, 44791, 12948, 211, 335, 43, 691, 62, 104, 2169, 439, 9, 10, 9, 8, 9, 14, 10, 13, 13, 11, 11, 10, 10, 12, 10, 10, 14, 4, 2, 4, 2, 5, 6, 7, 7, 8, 7, 6, 7, 5, 5, 7, 6, 5, 12, 5, 7, 8, 6, 6, 6, 4, 4, 6, 5, 2, 4, 4, 2, 6, 6, 3, 4, 6, 6, 4, 2, 4, 94]}
{'bbox_id': [168041, 168042, 168043, 168044, 168045, 168046, 168047], 'category': [10, 32, 35, 31, 4, 29, 33], 'bbox': [[238.0, 309.0, 471.0, 1022.0], [234.0, 572.0, 331.0, 602.0], [235.0, 580.0, 324.0, 599.0], [119.0, 318.0, 343.0, 856.0], [111.0, 262.0, 518.0, 1022.0], [166.0, 262.0, 393.0, 492.0], [238.0, 309.0, 278.0, 324.0]], 'area': [12132, 1548, 755, 43926, 178328, 9316, 136]}
{'bbox_id': [160050, 160051, 160052, 160053, 160054, 160055], 'category': [10, 31, 31, 23, 23, 33], 'bbox': [[290.0, 364.0, 429.0, 665.0], [304.0, 369.0, 397.0, 508.0], [290.0, 468.0, 310.0, 522.0], [213.0, 842.0, 294.0, 905.0], [446.0, 840.0, 536.0, 896.0], [311.0, 364.0, 354.0, 379.0]], 'area': [26873, 5301, 747, 1438, 1677, 71]}
{'bbox_id': [160056, 160057, 160058, 160059, 160060, 160061, 160062, 160063, 160064, 160065, 160066], 'category': [10, 36, 42, 42, 42, 42, 42, 42, 42, 23, 33], 'bbox': [[127.0, 198.0, 451.0, 949.0], [277.0, 336.0, 319.0, 402.0], [340.0, 343.0, 344.0, 347.0], [321.0, 338.0, 327.0, 343.0], [336.0, 361.0, 342.0, 365.0], [329.0, 321.0, 333.0, 326.0], [313.0, 294.0, 319.0, 300.0], [330.0, 299.0, 334.0, 304.0], [295.0, 330.0, 300.0, 334.0], [332.0, 926.0, 376.0, 946.0], [284.0, 198.0, 412.0, 270.0]], 'area': [137575, 1915, 14, 24, 18, 15, 25, 16, 16, 740, 586]}
{'bbox_id': [158963, 158964, 158965, 158966, 158967, 158968, 158969, 158970, 158971], 'category': [1, 31, 31, 7, 22, 22, 23, 23, 33], 'bbox': [[262.0, 449.0, 435.0, 686.0], [399.0, 471.0, 435.0, 686.0], [262.0, 451.0, 294.0, 662.0], [276.0, 603.0, 423.0, 726.0], [291.0, 759.0, 343.0, 934.0], [341.0, 749.0, 401.0, 947.0], [302.0, 919.0, 337.0, 994.0], [323.0, 925.0, 374.0, 1005.0], [343.0, 456.0, 366.0, 467.0]], 'area': [22330, 4422, 4846, 14000, 6190, 6997, 1547, 2107, 49]}
{'bbox_id': [158972, 158973, 158974, 158975, 158976], 'category': [23, 23, 28, 10, 5], 'bbox': [[412.0, 588.0, 451.0, 631.0], [333.0, 585.0, 357.0, 627.0], [361.0, 243.0, 396.0, 257.0], [303.0, 243.0, 447.0, 517.0], [330.0, 259.0, 425.0, 324.0]], 'area': [949, 737, 133, 17839, 2916]}

5. Filter Invalid Bboxes ❌
As the first step in preprocessing the dataset, we will filter out some invalid bounding boxes. After reviewing the dataset, we found that some bounding boxes did not have a valid structure. Therefore, we will discard these invalid entries.
Map: 0%| | 0/45623 [00:00<?, ? examples/s]
Image with invalid bbox: 8396 Invalid bbox detected and discarded: [0.0, 0.0, 0.0, 0.0] - bbox_id: 139952 - category: 42 Image with invalid bbox: 19725 Invalid bbox detected and discarded: [0.0, 0.0, 0.0, 0.0] - bbox_id: 23298 - category: 42 Image with invalid bbox: 19725 Invalid bbox detected and discarded: [0.0, 0.0, 0.0, 0.0] - bbox_id: 23299 - category: 42 Image with invalid bbox: 21696 Invalid bbox detected and discarded: [0.0, 0.0, 0.0, 0.0] - bbox_id: 277148 - category: 42 Image with invalid bbox: 23055 Invalid bbox detected and discarded: [0.0, 0.0, 0.0, 0.0] - bbox_id: 287029 - category: 33 Image with invalid bbox: 23671 Invalid bbox detected and discarded: [0.0, 0.0, 0.0, 0.0] - bbox_id: 290142 - category: 42 Image with invalid bbox: 26549 Invalid bbox detected and discarded: [0.0, 0.0, 0.0, 0.0] - bbox_id: 311943 - category: 37 Image with invalid bbox: 26834 Invalid bbox detected and discarded: [0.0, 0.0, 0.0, 0.0] - bbox_id: 309141 - category: 37 Image with invalid bbox: 31748 Invalid bbox detected and discarded: [0.0, 0.0, 0.0, 0.0] - bbox_id: 262063 - category: 42 Image with invalid bbox: 34253 Invalid bbox detected and discarded: [0.0, 0.0, 0.0, 0.0] - bbox_id: 315750 - category: 19
Map: 0%| | 0/1158 [00:00<?, ? examples/s]
Dataset({
features: ['image_id', 'image', 'width', 'height', 'objects'],
num_rows: 45623
})
Dataset({
features: ['image_id', 'image', 'width', 'height', 'objects'],
num_rows: 1158
})
6. Visualize Class Occurrences 👀
Let's explore the dataset further by plotting the occurrences of each class. This will help us understand the distribution of classes and identify any potential biases.
<ipython-input-66-aa111d1e000d>:14: UserWarning: FixedFormatter should only be used together with FixedLocator ax.set_xticklabels(categories, rotation=90, ha='right')

We can observe that some classes, such as "shoe" or "sleeve," are overrepresented in the dataset. This indicates that the dataset may have an imbalance, with certain classes appearing more frequently than others. Identifying these imbalances is crucial for addressing potential biases in model training.
7. Add Data Augmentation to the Dataset
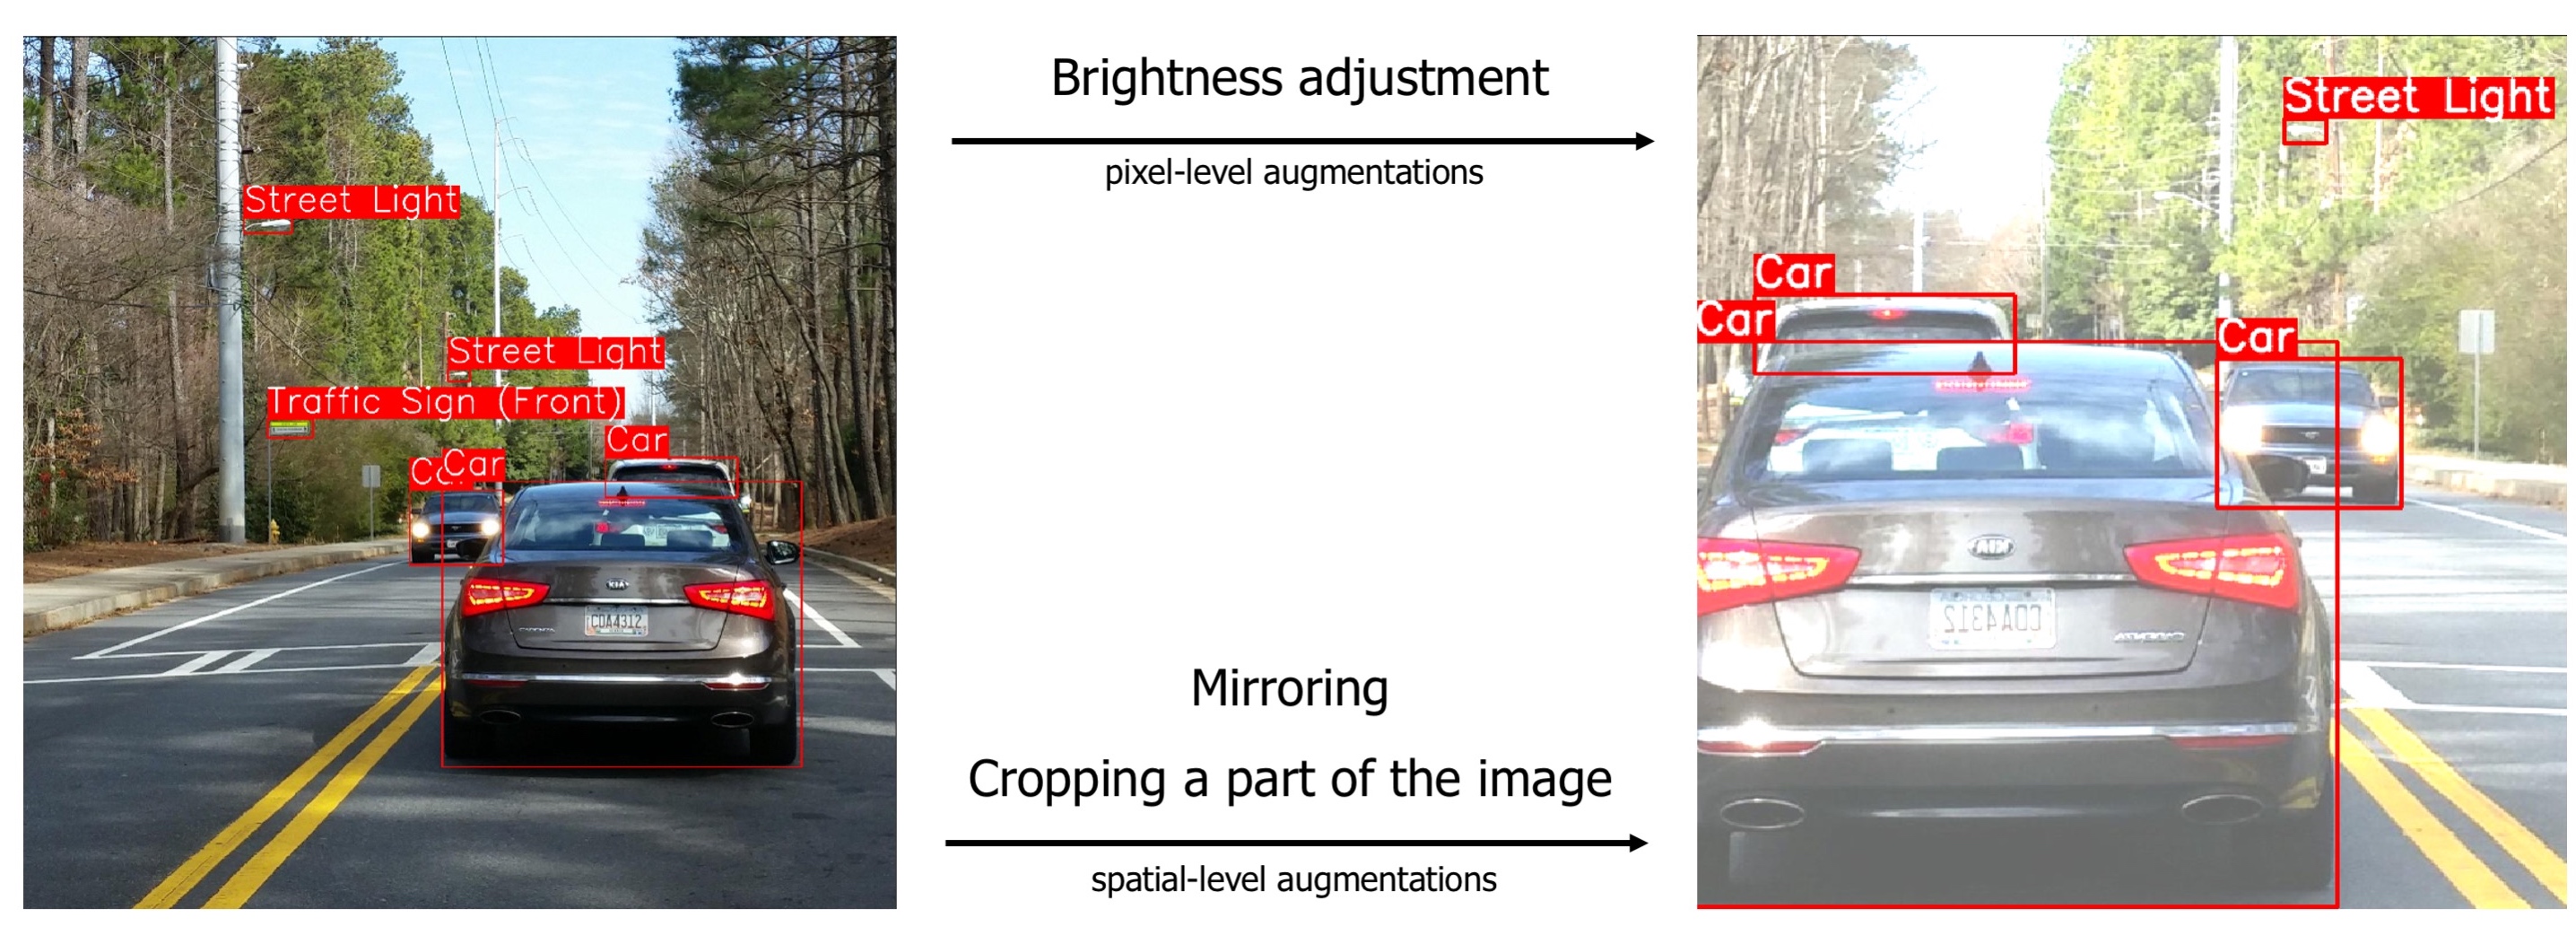
Data augmentation 🪄 is crucial for enhancing performance in object detection tasks. In this section, we will leverage the capabilities of Albumentations to augment our dataset effectively.
Albumentations provides a range of powerful augmentation techniques tailored for object detection. It allows for various transformations, all while ensuring that bounding boxes are accurately adjusted. These capabilities help in generating a more diverse dataset, improving the model’s robustness and generalization.
8. Initialize Image Processor from Model Checkpoint 🎆
We will instantiate the image processor using a pretrained model checkpoint. In this case, we are using the facebook/detr-resnet-50-dc5 model.
preprocessor_config.json: 0%| | 0.00/274 [00:00<?, ?B/s]
The `max_size` parameter is deprecated and will be removed in v4.26. Please specify in `size['longest_edge'] instead`.
Adding Methods to Process the Dataset
We will now add methods to process the dataset. These methods will handle tasks such as transforming images and annotations to ensure they are compatible with the model.
9. Plot Augmented Examples 🎆
We are nearing the model training phase! Before proceeding, let’s visualize some samples after augmentation. This will allow us to double-check that the augmentations are suitable and effective for the training process.

10. Initialize Model from Checkpoint
We will initialize the model using the same checkpoint as the image processor. This involves loading a pretrained model that we will fine-tune for our specific dataset.
10. Connect to HF Hub to Upload Fine-Tuned Model 🔌
We will connect to the Hugging Face Hub to upload our fine-tuned model. This allows us to share and deploy the model for others to use or for further evaluation.
11. Set Training Arguments, Connect to W&B, and Train!
Next, we will set up the training arguments, connect to Weights & Biases (W&B), and start the training process. W&B will help us track experiments, visualize metrics, and manage our model training workflow.
Connect to W&B to Track Training
Let's Train the Model! 🚀
Now it’s time to start training the model. Let’s run the training process and watch how our fine-tuned model learns from the data!
First, we declare the compute_metrics method for calculating the metrics on evaluation.
12. Test How the Model Behaves on a Test Image 📝
Now that the model is trained, we can evaluate its performance on a test image. Since the model is available as a Hugging Face model, making predictions is straightforward. In the following cell, we will demonstrate how to run inference on a new image and assess the model's capabilities.
Now, Let's Show the Results
We’ll display the results of the model’s predictions on the test image. This will give us insight into how well the model performs and highlight its strengths and areas for improvement.