17 Fine Tune Wav2vec2 For English Asr

Fine-tuning Wav2Vec2 for English ASR with 🤗 Transformers
Wav2Vec2 is a pretrained model for Automatic Speech Recognition (ASR) and was released in September 2020 by Alexei Baevski, Michael Auli, and Alex Conneau.
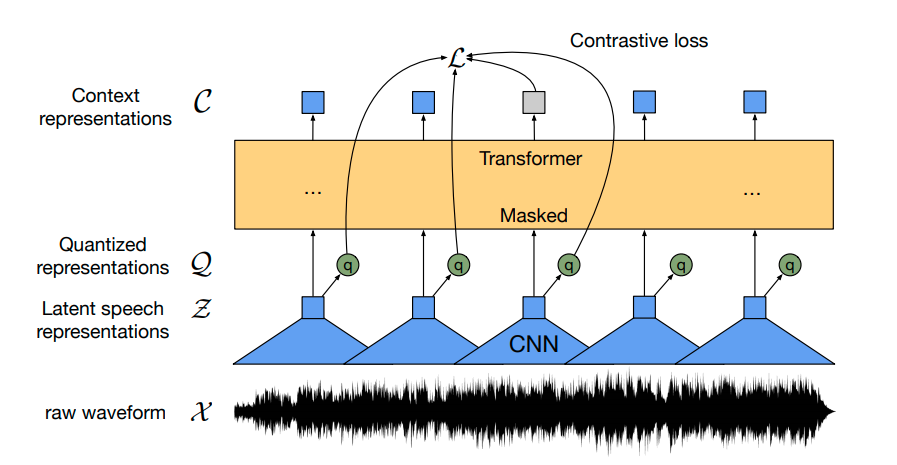
Using a novel contrastive pretraining objective, Wav2Vec2 learns powerful speech representations from more than 50.000 hours of unlabeled speech. Similar, to BERT's masked language modeling, the model learns contextualized speech representations by randomly masking feature vectors before passing them to a transformer network.
For the first time, it has been shown that pretraining, followed by fine-tuning on very little labeled speech data achieves competitive results to state-of-the-art ASR systems. Using as little as 10 minutes of labeled data, Wav2Vec2 yields a word error rate (WER) of less than 5% on the clean test set of LibriSpeech - cf. with Table 9 of the paper.
In this notebook, we will give an in-detail explanation of how Wav2Vec2's pretrained checkpoints can be fine-tuned on any English ASR dataset. Note that in this notebook, we will fine-tune Wav2Vec2 without making use of a language model. It is much simpler to use Wav2Vec2 without a language model as an end-to-end ASR system and it has been shown that a standalone Wav2Vec2 acoustic model achieves impressive results. For demonstration purposes, we fine-tune the "base"-sized pretrained checkpoint on the rather small Timit dataset that contains just 5h of training data.
Wav2Vec2 is fine-tuned using Connectionist Temporal Classification (CTC), which is an algorithm that is used to train neural networks for sequence-to-sequence problems and mainly in Automatic Speech Recognition and handwriting recognition.
I highly recommend reading the blog post Sequence Modeling with CTC (2017) very well-written blog post by Awni Hannun.
Before we start, let's install both datasets and transformers from master. Also, we need the soundfile package to load audio files and the jiwer to evaluate our fine-tuned model using the word error rate (WER) metric .
Timit is usually evaluated using the phoneme error rate (PER), but by far the most common metric in ASR is the word error rate (WER). To keep this notebook as general as possible we decided to evaluate the model using WER.
Prepare Data, Tokenizer, Feature Extractor
ASR models transcribe speech to text, which means that we both need a feature extractor that processes the speech signal to the model's input format, e.g. a feature vector, and a tokenizer that processes the model's output format to text.
In 🤗 Transformers, the Wav2Vec2 model is thus accompanied by both a tokenizer, called Wav2Vec2CTCTokenizer, and a feature extractor, called Wav2Vec2FeatureExtractor.
Let's start by creating the tokenizer responsible for decoding the model's predictions.
Create Wav2Vec2CTCTokenizer
The pretrained Wav2Vec2 checkpoint maps the speech signal to a sequence of context representations as illustrated in the figure above. A fine-tuned Wav2Vec2 checkpoint needs to map this sequence of context representations to its corresponding transcription so that a linear layer has to be added on top of the transformer block (shown in yellow). This linear layer is used to classifies each context representation to a token class analogous how, e.g., after pretraining a linear layer is added on top of BERT's embeddings for further classification - cf. with "BERT" section of this blog post.
The output size of this layer corresponds to the number of tokens in the vocabulary, which does not depend on Wav2Vec2's pretraining task, but only on the labeled dataset used for fine-tuning. So in the first step, we will take a look at Timit and define a vocabulary based on the dataset's transcriptions.
Let's start by loading the dataset and taking a look at its structure.
Reusing dataset timit_asr (/root/.cache/huggingface/datasets/timit_asr/clean/2.0.1/e7245f262bb418c1a5c67d67e00297322b1ad19eb65223676b790aa8003449e4)
DatasetDict({
,    train: Dataset({
,        features: ['file', 'text', 'phonetic_detail', 'word_detail', 'dialect_region', 'sentence_type', 'speaker_id', 'id'],
,        num_rows: 4620
,    })
,    test: Dataset({
,        features: ['file', 'text', 'phonetic_detail', 'word_detail', 'dialect_region', 'sentence_type', 'speaker_id', 'id'],
,        num_rows: 1680
,    })
,})
Many ASR datasets only provide the target text, 'text' for each audio file 'file'. Timit actually provides much more information about each audio file, such as the 'phonetic_detail', etc., which is why many researchers choose to evaluate their models on phoneme classification instead of speech recognition when working with Timit. However, we want to keep the notebook as general as possible, so that we will only consider the transcribed text for fine-tuning.
Let's write a short function to display some random samples of the dataset and run it a couple of times to get a feeling for the transcriptions.
Alright! The transcriptions look very clean and the language seems to correspond more to written text than dialogue. This makes sense taking into account that Timit is a read speech corpus.
We can see that the transcriptions contain some special characters, such as ,.?!;:. Without a language model, it is much harder to classify speech chunks to such special characters because they don't really correspond to a characteristic sound unit. E.g., the letter "s" has a more or less clear sound, whereas the special character "." does not.
Also in order to understand the meaning of a speech signal, it is usually not necessary to include special characters in the transcription.
In addition, we normalize the text to only have lower case letters.
Loading cached processed dataset at /root/.cache/huggingface/datasets/timit_asr/clean/2.0.1/e7245f262bb418c1a5c67d67e00297322b1ad19eb65223676b790aa8003449e4/cache-8786d042d93f5901.arrow
Loading cached processed dataset at /root/.cache/huggingface/datasets/timit_asr/clean/2.0.1/e7245f262bb418c1a5c67d67e00297322b1ad19eb65223676b790aa8003449e4/cache-73fb97b02c12a61d.arrow
Good! This looks better. We have removed most special characters from transcriptions and normalized them to lower-case only.
In CTC, it is common to classify speech chunks into letters, so we will do the same here. Let's extract all distinct letters of the training and test data and build our vocabulary from this set of letters.
We write a mapping function that concatenates all transcriptions into one long transcription and then transforms the string into a set of chars.
It is important to pass the argument batched=True to the map(...) function so that the mapping function has access to all transcriptions at once.
HBox(children=(FloatProgress(value=0.0, max=1.0), HTML(value='')))
HBox(children=(FloatProgress(value=0.0, max=1.0), HTML(value='')))
Now, we create the union of all distinct letters in the training dataset and test dataset and convert the resulting list into an enumerated dictionary.
{' ': 21,
, "'": 13,
, 'a': 24,
, 'b': 17,
, 'c': 25,
, 'd': 2,
, 'e': 9,
, 'f': 14,
, 'g': 22,
, 'h': 8,
, 'i': 4,
, 'j': 18,
, 'k': 5,
, 'l': 16,
, 'm': 6,
, 'n': 7,
, 'o': 10,
, 'p': 19,
, 'q': 3,
, 'r': 20,
, 's': 11,
, 't': 0,
, 'u': 26,
, 'v': 27,
, 'w': 1,
, 'x': 23,
, 'y': 15,
, 'z': 12}
Cool, we see that all letters of the alphabet occur in the dataset (which is not really surprising) and we also extracted the special characters " " and '. Note that we did not exclude those special characters because:
- The model has to learn to predict when a word finished or else the model prediction would always be a sequence of chars which would make it impossible to separate words from each other.
- In English, we need to keep the
'character to differentiate between words, e.g.,"it's"and"its"which have very different meanings.
To make it clearer that " " has its own token class, we give it a more visible character |. In addition, we also add an "unknown" token so that the model can later deal with characters not encountered in Timit's training set.
Finally, we also add a padding token that corresponds to CTC's "blank token". The "blank token" is a core component of the CTC algorithm. For more information, please take a look at the "Alignment" section here.
30
Cool, now our vocabulary is complete and consists of 30 tokens, which means that the linear layer that we will add on top of the pretrained Wav2Vec2 checkpoint will have an output dimension of 30.
Let's now save the vocabulary as a json file.
In a final step, we use the json file to instantiate an object of the Wav2Vec2CTCTokenizer class.
Next, we will create the feature extractor.
Create Wav2Vec2 Feature Extractor
Speech is a continuous signal and to be treated by computers, it first has to be discretized, which is usually called sampling. The sampling rate hereby plays an important role in that it defines how many data points of the speech signal are measured per second. Therefore, sampling with a higher sampling rate results in a better approximation of the real speech signal but also necessitates more values per second.
A pretrained checkpoint expects its input data to have been sampled more or less from the same distribution as the data it was trained on. The same speech signals sampled at two different rates have a very different distribution, e.g., doubling the sampling rate results in data points being twice as long. Thus, before fine-tuning a pretrained checkpoint of an ASR model, it is crucial to verify that the sampling rate of the data that was used to pretrain the model matches the sampling rate of the dataset used to fine-tune the model.
Wav2Vec2 was pretrained on the audio data of LibriSpeech and LibriVox which both were sampling with 16kHz. Our fine-tuning dataset, Timit, was luckily also sampled with 16kHz. If the fine-tuning dataset would have been sampled with a rate lower or higher than 16kHz, we first would have had to up or downsample the speech signal to match the sampling rate of the data used for pretraining.
A Wav2Vec2 feature extractor object requires the following parameters to be instantiated:
feature_size: Speech models take a sequence of feature vectors as an input. While the length of this sequence obviously varies, the feature size should not. In the case of Wav2Vec2, the feature size is 1 because the model was trained on the raw speech signal .sampling_rate: The sampling rate at which the model is trained on.padding_value: For batched inference, shorter inputs need to be padded with a specific valuedo_normalize: Whether the input should be zero-mean-unit-variance normalized or not. Usually, speech models perform better when normalizing the inputreturn_attention_mask: Whether the model should make use of anattention_maskfor batched inference. In general, models should always make use of theattention_maskto mask padded tokens. However, due to a very specific design choice ofWav2Vec2's "base" checkpoint, better results are achieved when using noattention_mask. This is not recommended for other speech models. For more information, one can take a look at this issue. Important If you want to use this notebook to fine-tune large-lv60, this parameter should be set toTrue.
Great, Wav2Vec2's feature extraction pipeline is thereby fully defined!
To make the usage of Wav2Vec2 as user-friendly as possible, the feature extractor and tokenizer are wrapped into a single Wav2Vec2Processor class so that one only needs a model and processor object.
If one wants to re-use the just created processor and the fine-tuned model of this notebook, one can mount his/her google drive to the notebook and save all relevant files there. To do so, please uncomment the following lines.
We will give the fine-tuned model the name "wav2vec2-base-timit-demo".
Next, we can prepare the dataset.
Preprocess Data
So far, we have not looked at the actual values of the speech signal but just kept the path to its file in the dataset. Wav2Vec2 expects the audio file in the format of a 1-dimensional array, so in the first step, let's load all audio files into the dataset object.
Let's first check the serialization format of the downloaded audio files by looking at the first training sample.
{'file': '/root/.cache/huggingface/datasets/downloads/extracted/404950a46da14eac65eb4e2a8317b1372fb3971d980d91d5d5b221275b1fd7e0/data/TRAIN/DR4/MMDM0/SI681.WAV',
, 'text': 'would such an act of refusal be useful'}
Alright, the audio file is saved in the .WAV format. There are a couple of python-based libraries to read and process audio files, such as librosa, soundfile, and audioread.
librosa seems to be the most active and prominent library, but since it depends on soundfile for loading of audio files, we will just use soundfile directly in this notebook.
An audio file usually stores both its values and the sampling rate with which the speech signal was digitalized. We want to store both in the dataset and write a map(...) function accordingly.
Loading cached processed dataset at /root/.cache/huggingface/datasets/timit_asr/clean/2.0.1/e7245f262bb418c1a5c67d67e00297322b1ad19eb65223676b790aa8003449e4/cache-d62364ad6c54348a.arrow
Loading cached processed dataset at /root/.cache/huggingface/datasets/timit_asr/clean/2.0.1/e7245f262bb418c1a5c67d67e00297322b1ad19eb65223676b790aa8003449e4/cache-56cc1d7ddfadf361.arrow
Loading cached processed dataset at /root/.cache/huggingface/datasets/timit_asr/clean/2.0.1/e7245f262bb418c1a5c67d67e00297322b1ad19eb65223676b790aa8003449e4/cache-f216e24386e1da8c.arrow
Loading cached processed dataset at /root/.cache/huggingface/datasets/timit_asr/clean/2.0.1/e7245f262bb418c1a5c67d67e00297322b1ad19eb65223676b790aa8003449e4/cache-b56673f39314d2ce.arrow
Loading cached processed dataset at /root/.cache/huggingface/datasets/timit_asr/clean/2.0.1/e7245f262bb418c1a5c67d67e00297322b1ad19eb65223676b790aa8003449e4/cache-c9573eb9038002e4.arrow
Loading cached processed dataset at /root/.cache/huggingface/datasets/timit_asr/clean/2.0.1/e7245f262bb418c1a5c67d67e00297322b1ad19eb65223676b790aa8003449e4/cache-2f52436b24902d38.arrow
Loading cached processed dataset at /root/.cache/huggingface/datasets/timit_asr/clean/2.0.1/e7245f262bb418c1a5c67d67e00297322b1ad19eb65223676b790aa8003449e4/cache-6d02e1ff4d3e4ea0.arrow
Loading cached processed dataset at /root/.cache/huggingface/datasets/timit_asr/clean/2.0.1/e7245f262bb418c1a5c67d67e00297322b1ad19eb65223676b790aa8003449e4/cache-e1ed1a5dbe9768c1.arrow
Great, let's listen to a couple of audio files to better understand the dataset and verify that the audio was correctly loaded.
Note: You can click the following cell a couple of times to listen to different speech samples.
It can be heard, that the speakers change along with their speaking rate, accent, etc. Overall, the recordings sound relatively clear though, which is to be expected from a read speech corpus.
Let's do a final check that the data is correctly prepared, but printing the shape of the speech input, its transcription, and the corresponding sampling rate.
Note: You can click the following cell a couple of times to verify multiple samples.
Target text: she had your dark suit in greasy wash water all year
Input array shape: (52941,)
Sampling rate: 16000
Good! Everything looks fine - the data is a 1-dimensional array, the sampling rate always corresponds to 16kHz, and the target text is normalized.
Finally, we can process the dataset to the format expected by the model for training. We will again make use of the map(...) function.
First, we check that all data samples have the same sampling rate (of 16kHz).
Second, we extract the input_values from the loaded audio file. In our case, this includes only normalization, but for other speech models, this step could correspond to extracting, e.g. Log-Mel features.
Third, we encode the transcriptions to label ids.
Note: This mapping function is a good example of how the Wav2Vec2Processor class should be used. In "normal" context, calling processor(...) is redirected to Wav2Vec2FeatureExtractor's call method. When wrapping the processor into the as_target_processor context, however, the same method is redirected to Wav2Vec2CTCTokenizer's call method.
For more information please check the docs.
/usr/local/lib/python3.7/dist-packages/numpy/core/_asarray.py:83: VisibleDeprecationWarning: Creating an ndarray from ragged nested sequences (which is a list-or-tuple of lists-or-tuples-or ndarrays with different lengths or shapes) is deprecated. If you meant to do this, you must specify 'dtype=object' when creating the ndarray
  return array(a, dtype, copy=False, order=order)
Loading cached processed dataset at /root/.cache/huggingface/datasets/timit_asr/clean/2.0.1/e7245f262bb418c1a5c67d67e00297322b1ad19eb65223676b790aa8003449e4/cache-3df281eef23bc3c1.arrow
Loading cached processed dataset at /root/.cache/huggingface/datasets/timit_asr/clean/2.0.1/e7245f262bb418c1a5c67d67e00297322b1ad19eb65223676b790aa8003449e4/cache-52047d825659a924.arrow
Loading cached processed dataset at /root/.cache/huggingface/datasets/timit_asr/clean/2.0.1/e7245f262bb418c1a5c67d67e00297322b1ad19eb65223676b790aa8003449e4/cache-1f70d7c49783619f.arrow
Loading cached processed dataset at /root/.cache/huggingface/datasets/timit_asr/clean/2.0.1/e7245f262bb418c1a5c67d67e00297322b1ad19eb65223676b790aa8003449e4/cache-936caf85ca041338.arrow
Loading cached processed dataset at /root/.cache/huggingface/datasets/timit_asr/clean/2.0.1/e7245f262bb418c1a5c67d67e00297322b1ad19eb65223676b790aa8003449e4/cache-87a10c92f6977664.arrow
Loading cached processed dataset at /root/.cache/huggingface/datasets/timit_asr/clean/2.0.1/e7245f262bb418c1a5c67d67e00297322b1ad19eb65223676b790aa8003449e4/cache-33d22c0f5024ece3.arrow
Loading cached processed dataset at /root/.cache/huggingface/datasets/timit_asr/clean/2.0.1/e7245f262bb418c1a5c67d67e00297322b1ad19eb65223676b790aa8003449e4/cache-6bc71fc1cb0ffdc7.arrow
Loading cached processed dataset at /root/.cache/huggingface/datasets/timit_asr/clean/2.0.1/e7245f262bb418c1a5c67d67e00297322b1ad19eb65223676b790aa8003449e4/cache-5bdfcef0389777d3.arrow
Training & Evaluation
The data is processed so that we are ready to start setting up the training pipeline. We will make use of 🤗's Trainer for which we essentially need to do the following:
-
Define a data collator. In contrast to most NLP models, Wav2Vec2 has a much larger input length than output length. E.g., a sample of input length 50000 has an output length of no more than 100. Given the large input sizes, it is much more efficient to pad the training batches dynamically meaning that all training samples should only be padded to the longest sample in their batch and not the overall longest sample. Therefore, fine-tuning Wav2Vec2 requires a special padding data collator, which we will define below
-
Evaluation metric. During training, the model should be evaluated on the word error rate. We should define a
compute_metricsfunction accordingly -
Load a pretrained checkpoint. We need to load a pretrained checkpoint and configure it correctly for training.
-
Define the training configuration.
After having fine-tuned the model, we will correctly evaluate it on the test data and verify that it has indeed learned to correctly transcribe speech.
Set-up Trainer
Let's start by defining the data collator. The code for the data collator was copied from this example.
Without going into too many details, in contrast to the common data collators, this data collator treats the input_values and labels differently and thus applies to separate padding functions on them (again making use of Wav2Vec2's context manager). This is necessary because in speech input and output are of different modalities meaning that they should not be treated by the same padding function.
Analogous to the common data collators, the padding tokens in the labels with -100 so that those tokens are not taken into account when computing the loss.
Next, the evaluation metric is defined. As mentioned earlier, the predominant metric in ASR is the word error rate (WER), hence we will use it in this notebook as well.
The model will return a sequence of logit vectors: with and .
A logit vector contains the log-odds for each word in the vocabulary we defined earlier, thus config.vocab_size. We are interested in the most likely prediction of the model and thus take the argmax(...) of the logits. Also, we transform the encoded labels back to the original string by replacing -100 with the pad_token_id and decoding the ids while making sure that consecutive tokens are not grouped to the same token in CTC style .
Now, we can load the pretrained Wav2Vec2 checkpoint. The tokenizer's pad_token_id must be to define the model's pad_token_id or in the case of Wav2Vec2ForCTC also CTC's blank token . To save GPU memory, we enable PyTorch's gradient checkpointing and also set the loss reduction to "mean".
Some weights of Wav2Vec2ForCTC were not initialized from the model checkpoint at facebook/wav2vec2-base and are newly initialized: ['lm_head.weight', 'lm_head.bias']
You should probably TRAIN this model on a down-stream task to be able to use it for predictions and inference.
The first component of Wav2Vec2 consists of a stack of CNN layers that are used to extract acoustically meaningful - but contextually independent - features from the raw speech signal. This part of the model has already been sufficiently trained during pretrainind and as stated in the paper does not need to be fine-tuned anymore.
Thus, we can set the requires_grad to False for all parameters of the feature extraction part.
In a final step, we define all parameters related to training. To give more explanation on some of the parameters:
group_by_lengthmakes training more efficient by grouping training samples of similar input length into one batch. This can significantly speed up training time by heavily reducing the overall number of useless padding tokens that are passed through the modellearning_rateandweight_decaywere heuristically tuned until fine-tuning has become stable. Note that those parameters strongly depend on the Timit dataset and might be suboptimal for other speech datasets.
For more explanations on other parameters, one can take a look at the docs.
Note: If one wants to save the trained models in his/her google drive the commented-out output_dir can be used instead.
Now, all instances can be passed to Trainer and we are ready to start training!
To allow models to become independent of the speaker rate, in CTC, consecutive tokens that are identical are simply grouped as a single token. However, the encoded labels should not be grouped when decoding since they don't correspond to the predicted tokens of the model, which is why the group_tokens=False parameter has to be passed. If we wouldn't pass this parameter a word like "hello" would incorrectly be encoded, and decoded as "helo".
The blank token allows the model to predict a word, such as "hello" by forcing it to insert the blank token between the two l's. A CTC-conform prediction of "hello" of our model would be [PAD] [PAD] "h" "e" "e" "l" "l" [PAD] "l" "o" "o" [PAD].
Training
Training will take between 90 and 180 minutes depending on the GPU allocated to this notebook. While the trained model yields satisfying results on Timit's test data, it is by no means an optimally fine-tuned model. The purpose of this notebook is to demonstrate how Wav2Vec2's base, large, and large-lv60 checkpoints can be fine-tuned on any English dataset.
In case you want to use this google colab to fine-tune your model, you should make sure that your training doesn't stop due to inactivity. A simple hack to prevent this is to paste the following code into the console of this tab (right mouse click -> inspect -> Console tab and insert code).
function ConnectButton(){
    console.log("Connect pushed");
    document.querySelector("#top-toolbar > colab-connect-button").shadowRoot.querySelector("#connect").click()
}
setInterval(ConnectButton,60000);
/usr/local/lib/python3.7/dist-packages/torch/optim/lr_scheduler.py:134: UserWarning: Detected call of `lr_scheduler.step()` before `optimizer.step()`. In PyTorch 1.1.0 and later, you should call them in the opposite order: `optimizer.step()` before `lr_scheduler.step()`.  Failure to do this will result in PyTorch skipping the first value of the learning rate schedule. See more details at https://pytorch.org/docs/stable/optim.html#how-to-adjust-learning-rate
  "https://pytorch.org/docs/stable/optim.html#how-to-adjust-learning-rate", UserWarning)
TrainOutput(global_step=4350, training_loss=0.5751241477878615, metrics={'train_runtime': 9534.5388, 'train_samples_per_second': 0.456, 'total_flos': 3.9858324576556134e+18, 'epoch': 30.0, 'init_mem_cpu_alloc_delta': 3558692, 'init_mem_gpu_alloc_delta': 380411904, 'init_mem_cpu_peaked_delta': 1617802440, 'init_mem_gpu_peaked_delta': 1511819264, 'train_mem_cpu_alloc_delta': 1357361, 'train_mem_gpu_alloc_delta': 1114656768, 'train_mem_cpu_peaked_delta': 126764054, 'train_mem_gpu_peaked_delta': 4098725376}) The final WER should be below 0.3 which is reasonable given that state-of-the-art phoneme error rates (PER) are just below 0.1 (see leaderboard) and that WER is usually worse than PER.
The resulting model of this notebook has been saved to patrickvonplaten/wav2vec2-base-timit-demo.
Evaluate
In the final part, we evaluate our fine-tuned model on the test set and play around with it a bit.
Let's load the processor and model.
Special tokens have been added in the vocabulary, make sure the associated word embedding are fine-tuned or trained.
Now, we will make use of the map(...) function to predict the transcription of every test sample and to save the prediction in the dataset itself. We will call the resulting dictionary "results".
Note: we evaluate the test data set with batch_size=1 on purpose due to this issue. Since padded inputs don't yield the exact same output as non-padded inputs, a better WER can be achieved by not padding the input at all.
HBox(children=(FloatProgress(value=0.0, max=1680.0), HTML(value='')))
Let's compute the overall WER now.
Test WER: 0.186
18.6% WER - not bad! Our model would have surely made the top 20 on the official leaderboard.
Let's take a look at some predictions to see what errors are made by the model.
It becomes clear that the predicted transcriptions are acoustically very similar to the target transcriptions, but often contain spelling or grammatical errors. This shouldn't be very surprising though given that we purely rely on Wav2Vec2 without making use of a language model.
Finally, to better understand how CTC works, it is worth taking a deeper look at the exact output of the model. Let's run the first test sample through the model, take the predicted ids and convert them to their corresponding tokens.
'[PAD] [PAD] [PAD] [PAD] [PAD] [PAD] t t h e e | | b b [PAD] u u n n n g g [PAD] a [PAD] [PAD] l l [PAD] o o o [PAD] | w w a a [PAD] s s | | [PAD] [PAD] p l l e e [PAD] [PAD] s s e n n t t t [PAD] l l y y | | | s s [PAD] i i [PAD] t t t [PAD] u u u u [PAD] [PAD] [PAD] a a [PAD] t t e e e d d d | n n e e a a a r | | t h h e | | s s h h h [PAD] o o o [PAD] o o r r [PAD] [PAD] [PAD] [PAD] [PAD] [PAD] [PAD] [PAD] [PAD] [PAD] [PAD]'
The output should make it a bit clearer how CTC works in practice. The model is to some extent invariant to speaking rate since it has learned to either just repeat the same token in case the speech chunk to be classified still corresponds to the same token. This makes CTC a very powerful algorithm for speech recognition since the speech file's transcription is often very much independent of its length.
I again advise the reader to take a look at this very nice blog post to better understand CTC.