111 Fine Tune Whisper

Fine-Tune Whisper For Multilingual ASR with 🤗 Transformers
In this Colab, we present a step-by-step guide on how to fine-tune Whisper for any multilingual ASR dataset using Hugging Face 🤗 Transformers. This is a more "hands-on" version of the accompanying blog post. For a more in-depth explanation of Whisper, the Common Voice dataset and the theory behind fine-tuning, the reader is advised to refer to the blog post.
Introduction
Whisper is a pre-trained model for automatic speech recognition (ASR) published in September 2022 by the authors Alec Radford et al. from OpenAI. Unlike many of its predecessors, such as Wav2Vec 2.0, which are pre-trained on un-labelled audio data, Whisper is pre-trained on a vast quantity of labelled audio-transcription data, 680,000 hours to be precise. This is an order of magnitude more data than the un-labelled audio data used to train Wav2Vec 2.0 (60,000 hours). What is more, 117,000 hours of this pre-training data is multilingual ASR data. This results in checkpoints that can be applied to over 96 languages, many of which are considered low-resource.
When scaled to 680,000 hours of labelled pre-training data, Whisper models demonstrate a strong ability to generalise to many datasets and domains. The pre-trained checkpoints achieve competitive results to state-of-the-art ASR systems, with near 3% word error rate (WER) on the test-clean subset of LibriSpeech ASR and a new state-of-the-art on TED-LIUM with 4.7% WER (c.f. Table 8 of the Whisper paper). The extensive multilingual ASR knowledge acquired by Whisper during pre-training can be leveraged for other low-resource languages; through fine-tuning, the pre-trained checkpoints can be adapted for specific datasets and languages to further improve upon these results. We'll show just how Whisper can be fine-tuned for low-resource languages in this Colab.
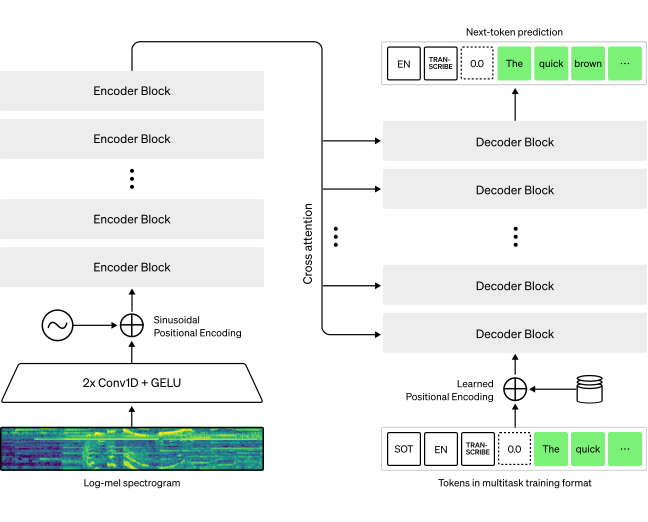
The Whisper checkpoints come in five configurations of varying model sizes. The smallest four are trained on either English-only or multilingual data. The largest checkpoint is multilingual only. All nine of the pre-trained checkpoints are available on the Hugging Face Hub. The checkpoints are summarised in the following table with links to the models on the Hub:
| Size | Layers | Width | Heads | Parameters | English-only | Multilingual |
|---|---|---|---|---|---|---|
| tiny | 4 | 384 | 6 | 39 M | ✓ | ✓ |
| base | 6 | 512 | 8 | 74 M | ✓ | ✓ |
| small | 12 | 768 | 12 | 244 M | ✓ | ✓ |
| medium | 24 | 1024 | 16 | 769 M | ✓ | ✓ |
| large | 32 | 1280 | 20 | 1550 M | x | ✓ |
For demonstration purposes, we'll fine-tune the multilingual version of the
"small" checkpoint with 244M params (~= 1GB).
As for our data, we'll train and evaluate our system on a low-resource language
taken from the Common Voice
dataset. We'll show that with as little as 8 hours of fine-tuning data, we can achieve
strong performance in this language.
\({}^1\) The name Whisper follows from the acronym “WSPSR”, which stands for “Web-scale Supervised Pre-training for Speech Recognition”.
Prepare Environment
First of all, let's try to secure a decent GPU for our Colab! Unfortunately, it's becoming much harder to get access to a good GPU with the free version of Google Colab. However, with Google Colab Pro one should have no issues in being allocated a V100 or P100 GPU.
To get a GPU, click Runtime -> Change runtime type, then change Hardware accelerator from None to GPU.
We can verify that we've been assigned a GPU and view its specifications:
Next, we need to update the Unix package ffmpeg to version 4:
We'll employ several popular Python packages to fine-tune the Whisper model.
We'll use datasets to download and prepare our training data and
transformers to load and train our Whisper model. We'll also require
the soundfile package to pre-process audio files, evaluate and jiwer to
assess the performance of our model. Finally, we'll
use gradio to build a flashy demo of our fine-tuned model.
We strongly advise you to upload model checkpoints directly the Hugging Face Hub whilst training. The Hub provides:
- Integrated version control: you can be sure that no model checkpoint is lost during training.
- Tensorboard logs: track important metrics over the course of training.
- Model cards: document what a model does and its intended use cases.
- Community: an easy way to share and collaborate with the community!
Linking the notebook to the Hub is straightforward - it simply requires entering your Hub authentication token when prompted. Find your Hub authentication token here:
Load Dataset
Using 🤗 Datasets, downloading and preparing data is extremely simple. We can download and prepare the Common Voice splits in just one line of code.
First, ensure you have accepted the terms of use on the Hugging Face Hub: mozilla-foundation/common_voice_11_0. Once you have accepted the terms, you will have full access to the dataset and be able to download the data locally.
Since Hindi is very low-resource, we'll combine the train and validation
splits to give approximately 8 hours of training data. We'll use the 4 hours
of test data as our held-out test set:
Most ASR datasets only provide input audio samples (audio) and the
corresponding transcribed text (sentence). Common Voice contains additional
metadata information, such as accent and locale, which we can disregard for ASR.
Keeping the notebook as general as possible, we only consider the input audio and
transcribed text for fine-tuning, discarding the additional metadata information:
Prepare Feature Extractor, Tokenizer and Data
The ASR pipeline can be de-composed into three stages:
- A feature extractor which pre-processes the raw audio-inputs
- The model which performs the sequence-to-sequence mapping
- A tokenizer which post-processes the model outputs to text format
In 🤗 Transformers, the Whisper model has an associated feature extractor and tokenizer, called WhisperFeatureExtractor and WhisperTokenizer respectively.
We'll go through details for setting-up the feature extractor and tokenizer one-by-one!
Load WhisperFeatureExtractor
The Whisper feature extractor performs two operations:
- Pads / truncates the audio inputs to 30s: any audio inputs shorter than 30s are padded to 30s with silence (zeros), and those longer that 30s are truncated to 30s
- Converts the audio inputs to log-Mel spectrogram input features, a visual representation of the audio and the form of the input expected by the Whisper model
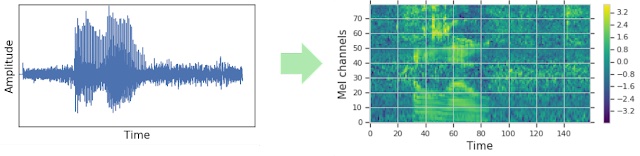
We'll load the feature extractor from the pre-trained checkpoint with the default values:
Load WhisperTokenizer
The Whisper model outputs a sequence of token ids. The tokenizer maps each of these token ids to their corresponding text string. For Hindi, we can load the pre-trained tokenizer and use it for fine-tuning without any further modifications. We simply have to specify the target language and the task. These arguments inform the tokenizer to prefix the language and task tokens to the start of encoded label sequences:
Downloading: 0%| | 0.00/829 [00:00<?, ?B/s]
Downloading: 0%| | 0.00/1.04M [00:00<?, ?B/s]
Downloading: 0%| | 0.00/494k [00:00<?, ?B/s]
Downloading: 0%| | 0.00/52.7k [00:00<?, ?B/s]
Downloading: 0%| | 0.00/2.11k [00:00<?, ?B/s]
Downloading: 0%| | 0.00/2.06k [00:00<?, ?B/s]
Combine To Create A WhisperProcessor
To simplify using the feature extractor and tokenizer, we can wrap
both into a single WhisperProcessor class. This processor object
inherits from the WhisperFeatureExtractor and WhisperProcessor,
and can be used on the audio inputs and model predictions as required.
In doing so, we only need to keep track of two objects during training:
the processor and the model:
Prepare Data
Let's print the first example of the Common Voice dataset to see what form the data is in:
Since our input audio is sampled at 48kHz, we need to downsample it to 16kHz prior to passing it to the Whisper feature extractor, 16kHz being the sampling rate expected by the Whisper model.
We'll set the audio inputs to the correct sampling rate using dataset's
cast_column
method. This operation does not change the audio in-place,
but rather signals to datasets to resample audio samples on the fly the
first time that they are loaded:
Re-loading the first audio sample in the Common Voice dataset will resample it to the desired sampling rate:
Now we can write a function to prepare our data ready for the model:
- We load and resample the audio data by calling
batch["audio"]. As explained above, 🤗 Datasets performs any necessary resampling operations on the fly. - We use the feature extractor to compute the log-Mel spectrogram input features from our 1-dimensional audio array.
- We encode the transcriptions to label ids through the use of the tokenizer.
We can apply the data preparation function to all of our training examples using dataset's .map method:
Training and Evaluation
Now that we've prepared our data, we're ready to dive into the training pipeline. The 🤗 Trainer will do much of the heavy lifting for us. All we have to do is:
-
Define a data collator: the data collator takes our pre-processed data and prepares PyTorch tensors ready for the model.
-
Evaluation metrics: during evaluation, we want to evaluate the model using the word error rate (WER) metric. We need to define a
compute_metricsfunction that handles this computation. -
Load a pre-trained checkpoint: we need to load a pre-trained checkpoint and configure it correctly for training.
-
Define the training configuration: this will be used by the 🤗 Trainer to define the training schedule.
Once we've fine-tuned the model, we will evaluate it on the test data to verify that we have correctly trained it to transcribe speech in Hindi.
Define a Data Collator
The data collator for a sequence-to-sequence speech model is unique in the sense that it
treats the input_features and labels independently: the input_features must be
handled by the feature extractor and the labels by the tokenizer.
The input_features are already padded to 30s and converted to a log-Mel spectrogram
of fixed dimension by action of the feature extractor, so all we have to do is convert the input_features
to batched PyTorch tensors. We do this using the feature extractor's .pad method with return_tensors=pt.
The labels on the other hand are un-padded. We first pad the sequences
to the maximum length in the batch using the tokenizer's .pad method. The padding tokens
are then replaced by -100 so that these tokens are not taken into account when
computing the loss. We then cut the BOS token from the start of the label sequence as we
append it later during training.
We can leverage the WhisperProcessor we defined earlier to perform both the
feature extractor and the tokenizer operations:
Let's initialise the data collator we've just defined:
Evaluation Metrics
We'll use the word error rate (WER) metric, the 'de-facto' metric for assessing ASR systems. For more information, refer to the WER docs. We'll load the WER metric from 🤗 Evaluate:
We then simply have to define a function that takes our model
predictions and returns the WER metric. This function, called
compute_metrics, first replaces -100 with the pad_token_id
in the label_ids (undoing the step we applied in the
data collator to ignore padded tokens correctly in the loss).
It then decodes the predicted and label ids to strings. Finally,
it computes the WER between the predictions and reference labels:
### Load a Pre-Trained Checkpoint
Now let's load the pre-trained Whisper small checkpoint. Again, this
is trivial through use of 🤗 Transformers!
Override generation arguments - no tokens are forced as decoder outputs (see forced_decoder_ids), no tokens are suppressed during generation (see suppress_tokens):
Define the Training Configuration
In the final step, we define all the parameters related to training. For more detail on the training arguments, refer to the Seq2SeqTrainingArguments docs.
Note: if one does not want to upload the model checkpoints to the Hub,
set push_to_hub=False.
We can forward the training arguments to the 🤗 Trainer along with our model,
dataset, data collator and compute_metrics function:
Training
Training will take approximately 5-10 hours depending on your GPU or the one allocated to this Google Colab. If using this Google Colab directly to fine-tune a Whisper model, you should make sure that training isn't interrupted due to inactivity. A simple workaround to prevent this is to paste the following code into the console of this tab (right mouse click -> inspect -> Console tab -> insert code).
function ConnectButton(){
    console.log("Connect pushed");
    document.querySelector("#top-toolbar > colab-connect-button").shadowRoot.querySelector("#connect").click()
}
setInterval(ConnectButton, 60000);
The peak GPU memory for the given training configuration is approximately 15.8GB.
Depending on the GPU allocated to the Google Colab, it is possible that you will encounter a CUDA "out-of-memory" error when you launch training.
In this case, you can reduce the per_device_train_batch_size incrementally by factors of 2
and employ gradient_accumulation_steps
to compensate.
To launch training, simply execute:
Our best WER is 32.0% - not bad for 8h of training data! We can submit our checkpoint to the hf-speech-bench on push by setting the appropriate key-word arguments (kwargs):
The training results can now be uploaded to the Hub. To do so, execute the push_to_hub command:
Building a Demo
Now that we've fine-tuned our model we can build a demo to show
off its ASR capabilities! We'll make use of 🤗 Transformers
pipeline, which will take care of the entire ASR pipeline,
right from pre-processing the audio inputs to decoding the
model predictions.
Running the example below will generate a Gradio demo where we can record speech through the microphone of our computer and input it to our fine-tuned Whisper model to transcribe the corresponding text:
Closing Remarks
In this blog, we covered a step-by-step guide on fine-tuning Whisper for multilingual ASR using 🤗 Datasets, Transformers and the Hugging Face Hub. For more details on the Whisper model, the Common Voice dataset and the theory behind fine-tuning, refere to the accompanying blog post. If you're interested in fine-tuning other Transformers models, both for English and multilingual ASR, be sure to check out the examples scripts at examples/pytorch/speech-recognition.